

The dominant narrative of AI progress in recent years has been model building larger models and feeding them more data. But for long-horizon agentic AI, model scaling alone is not the ultimate solution.
AI agents don’t get their abilities from next-token prediction alone but from the system that wraps around the model to translate its answers into real-world behavior.
The next major bottleneck in agentic AI is “system scaling,” or scaling the “harness,” according to a new paper from UC Berkeley. This approach treats the structured execution layer as a first-class object of design and optimization. As the author notes, “The dominant story of recent AI progress has been model scaling... For agentic AI, this story is now incomplete”.
Furthermore, “Once foundation models are embedded into tools, terminals, browsers, repositories, memory stores, and external services, their behavior is no longer determined by the model alone. It is determined by a system.”
This means when building and evaluating AI systems, we should move beyond just evaluating the model and look at the entire system and scaffolding as a whole and make sure every aspect is optimized for optimal performance.
Deconstructing the AI harness
Modern agent frameworks operate as robust system infrastructures rather than basic prompt wrappers. Under the hood, an agentic system can be factored into six interacting components. These components include:
A reasoning substrate that includes one or more LLMs
A memory store that keeps track of long-term information that the agent needs
A context constructor that builds and cleans up the information included in the model’s context window
A skill-routing layer that decides which skills should be involved in each substep of the agent’s solution
An orchestration loop that manages the sequence of operations and coordinates how the context constructor draws from memory to feed the foundation model
A verification-and-governance layer that acts as a gatekeeper for both intermediate reasoning and external actions, managing permissions, audit trails, and rollbacks, ensuring that outputs are checked before they are allowed to affect the live environment or be written back into the persistent memory store
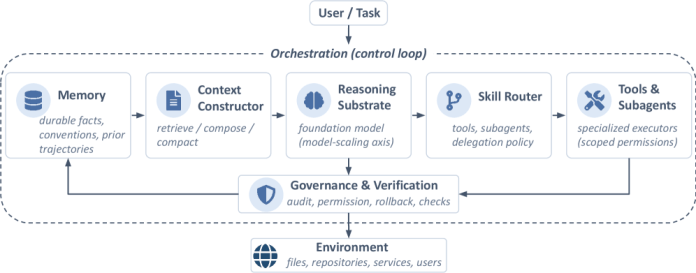
While different agent harnesses are built for different purposes and audiences, they usually converge on the same main components. Claude Code acts as a vendor coding tool, OpenClaw operates as a multi-channel personal assistant, and CheetahClaws serves as an open-source research reference harness. Yet, all three must actively manage context governance, memory storage, and skill routing.
The structural differences between these harnesses are driven by their specific deployment priorities, such as enterprise reliability versus open-source reproducibility, rather than changes to the underlying foundation model.
## The three layers of agent time
An AI system operates across distinct temporal scales to manage complex, long-term tasks. You can break this architecture down into three functional layers: prompts, skills, and memory.
Prompts operate strictly on a local, short-horizon timescale to define immediate goals. They dictate what the model should focus on in the current moment. However, prompts are fragile over extended execution lengths and transfer poorly to new scenarios.
Skills operate on a task-level timescale as reusable execution patterns or tool workflows. Think of a skill as a predefined routine for searching a database or editing a configuration file. While highly effective for executing specific tasks, skills introduce new challenges. When an agent has dozens of skills, chaining them to solve ambiguous problems introduces routing, composition, and delegation challenges.
Memory functions as the longitudinal layer that preserves facts across sessions. It allows an agent to remember user preferences or project architectures weeks after the first interaction. However, memory is vulnerable to degradation, contamination, and over-generalization over time.
The three major bottlenecks of system scaling
Building a reliable autonomous agent requires solving three specific engineering roadblocks: context governance, trustworthy memory, and dynamic skill routing.
Expanding context capacity does not fix relevance. Unfiltered inputs create signal dilution, causing the model to suffer from an “exposure without access” failure where it misses crucial data buried in padding. Even LLMs that support million-token context windows suffer from context rot when their prompts become long and filled with conflicting information and data that are not relevant to the task at hand.
Context assembly must act as a strict selection policy that optimizes for a minimum sufficient context. “The hard problem of context is not capacity, but governance,” the paper notes, adding that “Long context does not indicate good context; tokens added without governance often degrade performance rather than improve it”.
Real-world tools prevent context flooding by employing aggressive management mechanisms. Recent architectural analyses of Claude Code reveal a five-tier compaction system. This includes routines like “micro-compact” for cleaning up old tool results and “context collapse” for summarizing long dialogue spans.
Furthermore, when tools emit massive text outputs (e.g., an endless server error log) the system avoids token bloating by writing the full file to the local disk and supplying only an 8-kilobyte preview to the LLM. This forces the model to act like a human developer, scanning the top of the log and only digging deeper if necessary.
Agent memory faces a completely different challenge: the “stale-but-confident” threat. This occurs when an agent erroneously tracks high-ranking semantic results that are completely outdated due to silent external drift. An agent might read an old note about how a codebase is structured, fail to realize the code was refactored yesterday, and confidently break the application. “The hard problem of agent memory is not storage, but trust,” the paper warns. Memory trust can only be sustained via just-in-time verification against the live environment.
Structurally, this is achieved via a “skeptical memory” framework. In Claude Code, an index file like MEMORY.md is treated strictly as an unverified pointer or hint. The agent is programmatically forced to verify the memory’s claims against the live file system before taking any destructive action. Additionally, systems maintain long-term memory hygiene by running background daemons like autoDream during idle times to resolve contradictions, compress insights, and bound memory growth before the agent degrades.
Finally, multi-agent configurations suffer from a “confident-but-unchecked” vulnerability. In this scenario, a specialized routing branch outputs highly plausible but completely unverified answers. “The hard problem of skill is not having skills, but routing and checking them,” the paper warns. Harness engineering must tie skill selection directly to explicit post-condition checks to guarantee reliability.
Evaluating and governing the evolving agent
Evaluating systems solely via one-shot outcome metrics, such as simple task success rates, masks hidden systemic liabilities. These hidden liabilities include high token costs, excessive tool-call latencies, and high retry errors. In a real-world deployment, an agent that brute-forces its way to a solution through endless retries wastes compute and risks API rate-limiting. Evaluation protocols must integrate process metrics that measure trajectory hygiene, verification overhead, and context efficiency over extended steps.
Multi-agent arrangements can open parallel processing windows, but genuine collaboration breaks down without a standardized communication layer for state sharing, contradiction spotting, and uncertainty reporting. “A one-shot evaluation cannot reveal whether an agent’s memory becomes more useful, more noisy, or more dangerous over repeated use,” the paper notes.
To safeguard agents against persistent threats like memory poisoning and goal manipulation, a concrete governance standard must define exactly what persists, what updates, and what leaves an unalterable audit trail. “Without such standards, many so-called learning agents risk becoming opaque accumulations of prompts, notes, and heuristics rather than reliable adaptive systems,” the paper writes.
While raw frontier-model reasoning capabilities remain indispensable, model capability alone is no longer an adequate baseline for evaluating or predicting agent success. “Agentic AI is moving from isolated model inference to persistent system execution,” per the paper.
The long-term roadmap of the AI sector will be defined by how securely and efficiently systems manage what the model remembers, what it retrieves, what actions it permits, and what it leaves fully auditable. “Scaling the harness, alongside scaling the model, defines the next major bottleneck of agentic AI,” the paper concludes.
In other words, success is determined by precise attention to the current problem and adaptation to it, with the pre-trainined model serving only as a rulebook of various strategies. Just as people do things.
The good news is that people working with AI agents now provide very invaluable data for how people actually solve problems. This will be baked into training, and will give future AI more ideas.
Need a lot more work for measuring things on the job and recovery from failure. Then sure, how to make agents collaborate and how to collaborate better with people too.
I’m really happy to see this thinking, as for me this has been pretty obviously the path for SW Dev’p for 18 months or more, but I think there are at least three other significant factors:
Managing the cognitive offload to relevant humans
Capturing tacit knowledge of the organizational-experience space
Tightening the feedback loop
I saw an interesting post go by today noting that software is 6x the usage of other AI use cases, and larger than the rest combined. For me, this is perfectly predictable, due in part to the factors above.
For users to effectively use AI, the degree of adaptation by humans to the way AI works, and the pattern of what the tool effectively offloads to human cognition, is important. As an example, imperfect automated vehicles handle the mundane driving tasks but require humans to intervene for oddball situations, mistakes, and emergencies; this is a truly crappy approach, as the human will lack situational awareness and not be attentive when they aren’t always in the mundane loop also.
For software dev’p, the user can set work in motion, the AI can go do work, and the human can review (or not). As long as the framework is robust, roll-back is possible, and as long as the task is well-scoped it should be more or less testable, and any generated code should be more or less readable. There may still be awareness gaps and complacency, but these don’t get multiplied by real-time response demands and physical risk. Plus, humans have for a long time had to do some spec work, split up tasks, refine and decompose, implement and integrate, test in umpteen ways, and manage change operations throughout - it’s not really “new” merely “different”.
And this means that the evolving SW dev’p frameworks will already capture a lot of the tacit knowledge of development because the tools have already evolved to offload drudgery AND all the tools and processes are pretty well captured digitally and with solid visibility to AI training.
That brings us to the second point: software tools and software development has a hefty Venn overlap with AI itself, and with the AI developers, so it is only natural that tacit knowledge gets in-built for software work early, and the training data is pretty quickly assessed and curated. We already know how to manage work across global teams with new Devs and Testers speaking various languages and with time mismatches, so loose batch-work that is rigorous on process is not a stretch…even if the result is that many will then “vibe code” and leave much of the rigor at the whim of the AI (not a perfect plan, naturally).
The last point is having a tight improvement cycle from tool devp to end-user feedback for rapid iteration, and again this is where the Venn overlap and in-company use of AI for SW dev’p makes the big impacts. The desire for all major AI companies is to have self-improving AIs, which implies also self-improving development tools. There is a huge goal alignment and value capture in this context.
Put it all together with your other scaling factors, and we are going to first see AI get really good at AI, and then those tools will be used to build the frameworks for other domains, and then those will also interate and improve. The domains with easy digital capture of knowledge and know-how of course will be easier, and those where the human-factor offloading readily matches user aptitudes also. Finally, the domains where users and vendors have a tight cycle will make progress first.
Long-lead projects like medical equipment manufacturing with lengthy certifications for tools and products, sciences like agriculture where growing seasons are needed to test and to then scale, and domains where human labor or manufacturing is needed to iterate will go more slowly.
As for when? Software is coming fast, and a few years of massive improvement is already baked-in as models gain leverage. Hang on to your hat!